By Oleksii Tkachuk, Rajiv Shringi, Chris Lohfink, Abe Ratnofsky, Kartik SathyanarayananIntroductionIn an earlier post, we introduced the TimeSeries Abstraction, our high-throughput, low-latency...
Cloudflare has launched K2 in public beta, a serverless event streaming service implementing a durable log on R2 object storage. Cloudflare states produce latency of about one second at p99; a...
Grab migrated its high-volume Counter Service from a wide column database to Aerospike using storage abstraction, shadow traffic, data parity validation, and gradual traffic migration. The...
Cursor has introduced Continuity, a Git storage architecture that uses an S3 backed write ahead log as the source of truth. The design turns local NVMe repositories into warm caches and separates...
Perplexity has migrated its search infrastructure from Amazon DynamoDB to CobbleDB, an internally developed key-value store in Rust. This change reduced latency and costs associated with handling...
Cloudflare recently described a prototype called Cache Transcoding that compresses eligible cache content, mainly uncompressed text such as HTML, JSON, CSS, and JavaScript, using Zstandard before...
kube-apiserver通过storage.Interface与etcd交互,存储protobuf序列化数据,key由前缀拼接,value经Transformer加密。GuaranteedUpdate用etcd Txn实现乐观并发写,Create/Delete/Watch各有路径。排障需关注etcd延迟、转换失败等指标,区分apiserver与etcd问题。
本文介绍kube-apiserver排障方法,提出五轴坐标系:Storage/etcd、Watch/cache、Admission、Auth、APF。通过症状映射表快速定位问题轴,如401/403查Auth,503查Admission,504查APF,410查Watch。强调先定轴再下钻,避免误操作,并列出关键metrics和命令,区分apiserver与etcd问题,指导高效排障。
本文介绍kube-apiserver生产内核系列,聚焦控制面故障排障,以Storage/Watch/Admission/Auth/APF五轴为坐标系,规划16篇阅读路线。内容涵盖请求路径、watch cache、resourceVersion、Webhook、APF等机制,版本锚定Kubernetes v1.30.3,旨在帮助SRE归因504、410等错误,区分直连etcd与apiserver排障边界。
CloudJump III 提出引擎集成分层存储方案,将数据放置决策融入存储引擎,利用页类型、存活时间等元信息优化冷热数据分布。通过BPE缓存准入策略、OSS Buffer写合并及快照版本协议,实现性能稳定、成本优化和零停机备份,显著提升单位成本性能。
AWS Lambda can now reference deployment packages directly in customer-owned S3 buckets, removing the per-Region code storage quota and raising the managed default from 75 GB to 300 GB....
DoltHub has recently released Dolt 2.0, a major update to the open source version-controlled SQL database. The latest major version adds automatic storage optimization, including garbage...
本文讨论了FoundationDB的存储架构,重点在于客户端如何直接读取Storage Server,绕过Proxy和Resolver。每个Storage Server管理多个shard,支持异步复制。客户端通过缓存的元数据定位数据,并在5秒内读取版本。文章还探讨了数据迁移、负载均衡机制,以及读路径设计如何提高性能和一致性。
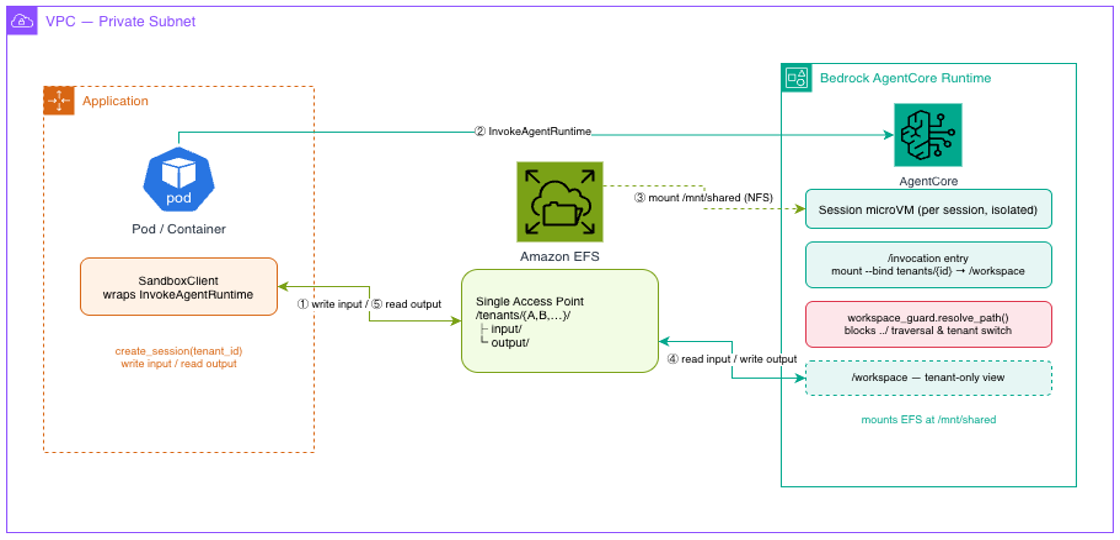
Amazon Bedrock AgentCore 提供三种持久化文件系统:Managed Session Storage、Amazon EFS 和 S3 Files,分别适用于个人私有数据、多方共享和写少读多的场景。用户可根据需求选择合适的存储方案。
Phase 1 gave us in-memory vectors and data chunks. But a database needs to persist data to disk and read it back. The challenge is designing a disk format that preserves the benefits of columnar...
SIG Storage是Kubernetes的一个特别兴趣小组,专注于持久数据和存储管理。随着状态工作负载的增加,SIG Storage推出了Volume Group Snapshot和Changed Block Tracking等新功能,以提升数据保护和备份效率。未来将关注智能数据管理和对象存储,以满足AI工作负载的需求。
AWS has recently introduced durability for Amazon ElastiCache for Valkey, enabling reliable data retention across failures and expanding support beyond caching to persistent workloads. The feature...
AWS recently announced ExtendDB, a DynamoDB-compatible adapter that lets developers use the DynamoDB API with different storage backends, starting with PostgreSQL. The project supports existing...
This article explores Kafka's transition toward a cloud-native architecture, examining how tiered storage, FinOps telemetry, elastic consumer scaling, virtual clusters, and Share Groups reshape...
Every time-series database makes a set of storage design decisions: how to lay out rows, when to compress, what to partition on. These decisions determine cost and query performance more than the...
完成下面两步后,将自动完成登录并继续当前操作。